
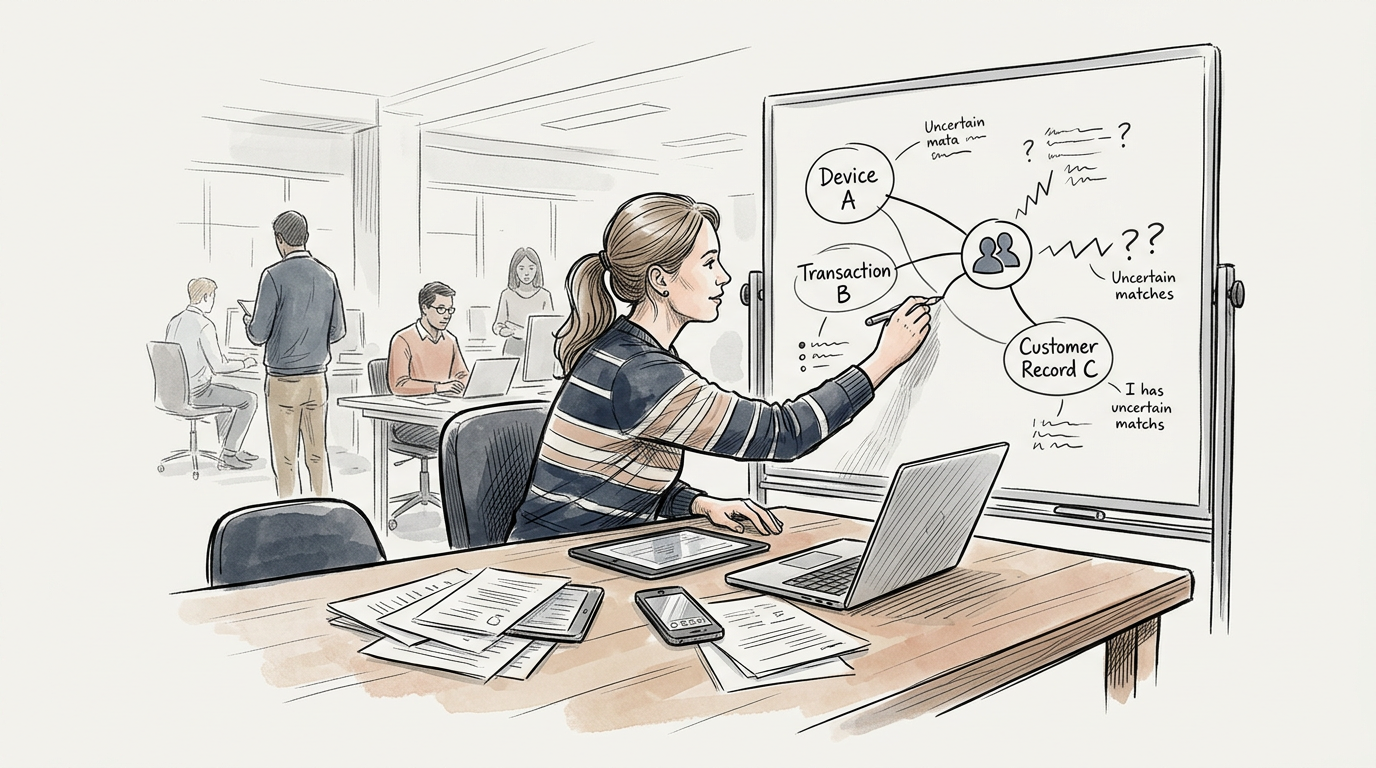
Identity resolution sits underneath many of the promises made by modern marketing technology. Personalization, frequency management, audience measurement, customer journey analysis, loyalty orchestration, retail media activation, and cross-channel attribution all depend on a basic operational question: when two interactions appear in different systems, do they belong to the same person, household, or customer account?
That question sounds straightforward until organizations try to answer it at scale. A consumer may browse a product on a work laptop, open a promotional email on a phone, purchase through a retailer marketplace under a different email address, call customer service from a family-shared number, and appear in an offline CRM record with yet another identifier. Each of those events may be real, valuable, and measurable on its own. Connecting them accurately is much harder.
Identity resolution is the set of processes and technologies used to link those records. It is not a single product feature, and it is not the same thing as third-party cookie targeting. In practice, it combines data collection, matching logic, confidence scoring, privacy controls, and ongoing maintenance. For advertising and marketing professionals, it matters because nearly every claim about reaching the right audience, reducing waste, or understanding performance depends on whether these links are reliable.
What identity resolution actually does
At a practical level, identity resolution attempts to determine when multiple identifiers refer to the same entity. Depending on the use case, that entity might be an individual consumer, a household, a business account, or a device cluster.
The identifiers involved can include email addresses, phone numbers, login credentials, mobile ad IDs, customer IDs, postal addresses, browser cookies, loyalty numbers, device fingerprints where permitted, and platform-specific identifiers from media and commerce environments. Identity systems also often rely on event data such as purchases, site visits, app sessions, store visits, and customer service interactions.
The goal is usually to create some form of identity graph, meaning a data structure that maps relationships among identifiers and records over time. A customer data platform, CRM system, data clean room, retail media platform, identity vendor, or internal data warehouse may maintain some version of that graph.
For marketers, the business uses are familiar:
- Suppressing ads to recent purchasers
- Coordinating messaging across email, paid media, SMS, and customer service
- Limiting duplicate outreach when one person appears in multiple systems
- Measuring campaign reach and frequency more realistically
- Building audience segments from first-party data
- Matching loyalty or CRM records to media exposures in privacy-constrained environments
- Reducing fragmentation in reporting across channels and platforms
None of this means a company has a perfect single view of the customer. It means the organization is trying to increase the odds that separate signals can be tied together usefully enough for a particular marketing or analytics purpose.
Why the problem has become more difficult
Identity resolution is not new, but the operating environment has changed. Marketing teams now work across more channels, more logins, more devices, more walled platforms, and more privacy restrictions than they did when cookie-based web tracking dominated digital media.
Browser-level support for third-party cookies has declined significantly. Apple’s App Tracking Transparency framework changed how mobile app tracking works by requiring user permission to access the Identifier for Advertisers, or IDFA, across apps and websites owned by other companies, reducing the availability of that identifier for many advertisers and data brokers. Major browsers have also tightened rules around cross-site tracking and storage access. Regulators in multiple jurisdictions have expanded consent, disclosure, access, deletion, and data minimization requirements under laws such as the EU’s General Data Protection Regulation and California’s privacy laws. At the same time, consumers interact with brands across connected TV, retail media networks, in-store systems, mobile apps, marketplaces, loyalty programs, social platforms, and customer service channels that often do not share identifiers directly.
The result is a fragmented environment in which marketers still want continuity, but the technical and legal conditions for stitching records together are more constrained.
Deterministic matching: high confidence, narrower coverage
The clearest form of identity resolution is deterministic matching. This approach links records when the system has a direct, concrete basis for believing they belong together.
Common deterministic signals include:
- The same person logs into a brand’s website and mobile app with the same account
- An email address captured in ecommerce matches an email address in the CRM
- A loyalty number appears in both point-of-sale and customer support records
- A hashed email is matched between a brand and a media partner under agreed terms
- A household postal address matches across subscription and transaction databases
Deterministic methods are generally more reliable than looser forms of inference because they depend on explicit shared identifiers or verified account relationships. If a consumer uses the same authenticated login in multiple environments, the organization can often connect those interactions with relatively high confidence, subject to the quality of the source data and the permissions under which it was collected.
This is one reason first-party data strategies have become so important. Brands, publishers, and retailers increasingly value authenticated relationships because they support more durable identity linkage than many forms of anonymous web tracking. That does not make deterministic identity simple. People use multiple email addresses, share devices, mistype form entries, create duplicate accounts, change phone numbers, and transact as guests. Even direct identifiers degrade over time.
Deterministic matching also has a coverage problem. It works best where users are known and authenticated. It becomes less useful when a large share of interactions are anonymous, when partners cannot exchange raw identifiers, or when legal and contractual restrictions limit data joining.
Probabilistic matching: broader reach, more uncertainty
Where direct matching is not possible, organizations may use probabilistic methods. These approaches infer that records are likely related based on patterns and statistical signals rather than explicit proof.
Probabilistic identity systems may consider combinations of factors such as IP address patterns, device characteristics, browser configurations, location consistency, timestamp patterns, behavioral similarities, and historical co-occurrence among identifiers. Machine learning can be used in some systems to estimate the probability that records belong to the same user or household.
In marketing practice, probabilistic matching is often used to extend reach, estimate cross-device relationships, support measurement models, or fill gaps where deterministic data is sparse. It can be useful, but it is inherently less certain.
This distinction matters because probabilistic matches are often described in business language that sounds firmer than the underlying method warrants. A vendor may claim to identify consumers across channels, but the actual process may involve confidence-weighted modeling rather than verified linkage. That does not mean the method is useless. It means the results should be interpreted as estimates, not confirmed facts.
For example, a probabilistic system might infer that a mobile device and a streaming TV in the same home are associated because they repeatedly appear on the same network and exhibit correlated timing patterns. That may be directionally useful for household-level reach estimation. It is not the same thing as proving that a specific individual who clicked an ad on one device later purchased on another.
In privacy-sensitive and measurement-driven environments, probabilistic techniques often survive where deterministic tracking does not. But they bring higher error risk, and those errors have practical consequences.
The difference between individual, household, and account identity
One source of confusion in identity discussions is that “same customer” can mean different things depending on the system.
An advertiser may want person-level targeting for email suppression, household-level measurement for connected TV, account-level orchestration for a subscription service, and location-level matching for store analytics. These are not interchangeable.
A household graph can be useful for media planning and reach estimation, especially in channels such as connected TV where viewing devices are commonly shared. But household-level identity can be misleading if it is treated as person-level knowledge. An ad shown on a living room television may be relevant to one member of a household and irrelevant to another. Similarly, a business account may involve multiple users, procurement roles, and billing contacts. Treating every identifier connected to an account as one person can distort both targeting and measurement.
Professionals evaluating identity products should ask what unit of identity the system is actually resolving. Many operational problems come from assuming a finer level of precision than the data supports.
A unified identity is a model, not a mirror of reality
Marketing language often refers to a “single customer view” as if customer identity exists in clean, stable form waiting to be assembled. In practice, unified identity is a constructed model built from incomplete, uneven, and time-sensitive data.
People change addresses, phones, jobs, devices, names, and purchase patterns. They use privacy tools, clear cookies, browse in different contexts, and sometimes intentionally separate identities for work, family, and commerce. Data entry errors create duplicates. Mergers bring overlapping records from incompatible systems. Offline and online identifiers do not always reconcile neatly. Even within one company, different business units may define a customer differently.
That means identity resolution is not a one-time integration project. It is an ongoing process of matching, confidence scoring, governance, and correction. The graph must be updated as relationships appear, disappear, or become less trustworthy. Rules that looked sensible at launch may create false merges months later.
This is why organizations that promise a fully unified customer identity across all touchpoints should be evaluated carefully. Some environments can support strong resolution in specific contexts, especially where logged-in activity and consented first-party data are abundant. But a universal, perfectly accurate identity layer across all marketing systems remains unrealistic.
What errors look like in practice
Identity resolution systems can fail in two broad ways. They can merge records that should remain separate, or they can fail to connect records that belong together.
False merges are often more damaging. If two people are incorrectly treated as one, a brand might suppress ads to a prospect because someone else in the inferred identity cluster purchased recently. A financial or healthcare message might be shown to the wrong family member. A loyalty offer could be misdirected, or a service issue could be attributed to the wrong customer history. In B2B marketing, two contacts at the same company might be collapsed into one account-level profile in ways that erase important differences in role and intent.
False splits create different problems. The same customer appears as multiple records, which can inflate reach estimates, distort frequency controls, weaken attribution, and trigger repetitive or contradictory messaging. A consumer might receive acquisition ads after becoming a customer simply because the purchase record did not resolve to the ad exposure record.
Neither problem is purely technical. Both affect budget efficiency, customer experience, campaign interpretation, and trust in analytics.
Why identity resolution matters for measurement
Some of the most important uses of identity resolution are analytical rather than activation-oriented. Marketers want to know how many people they reached, whether exposures happened before outcomes, how frequently the same person saw an ad, and how different channels contributed to conversion.
Those questions are difficult to answer when every platform reports in isolation. Identity resolution can improve deduplication across channels and reduce overcounting, especially when a brand is trying to combine CRM, web analytics, media exposure, commerce, and offline data. It also supports incrementality analysis, match-back studies, and customer journey reconstruction in cases where the underlying joins are sufficiently reliable and privacy-compliant.
Still, better identity does not automatically solve attribution. Even if a brand can connect an ad exposure to a later purchase, that link alone does not prove causation. Identity resolution helps establish whether events may belong to the same user or household. It does not determine whether the marketing caused the outcome. Those are separate analytical issues.
This distinction matters because identity vendors and martech platforms sometimes blur it. A cleaner identity graph can improve the quality of measurement inputs, but it does not turn observational data into definitive evidence of impact.
The infrastructure behind identity programs
In practice, identity resolution usually depends less on a single vendor algorithm than on data infrastructure choices.
Many organizations now maintain identity logic across multiple layers:
- A CRM or loyalty system with known customer identifiers
- A customer data platform or composable data layer that unifies profile attributes and event streams
- A data warehouse or lakehouse where matching rules are governed internally
- Consent and preference management systems that define allowed uses
- Media platform integrations that support audience onboarding or measurement
- Privacy-enhancing environments such as clean rooms for controlled data matching
This architecture matters because identity resolution is constrained by what data is collected, normalized, retained, and legally usable. If source systems are inconsistent, stale, or missing key fields, no matching model will fully compensate. If consent signals are not connected to identity logic, the organization may create compliance risk even if the technical match rates look impressive.
The rise of data clean rooms illustrates this shift. Clean rooms from major platforms and cloud providers can enable privacy-controlled analysis and matching between parties without exposing raw user-level data in the traditional way. They can be useful for measurement, overlap analysis, and audience insights. But they do not remove the underlying identity challenge. They simply change the environment in which matching occurs and often limit how granularly results can be activated.
Privacy and governance are not side issues
Identity resolution is deeply tied to privacy because it is fundamentally about linking data points that might otherwise remain separate.
Whether a company can legally and ethically perform that linking depends on jurisdiction, data type, consent framework, contractual restrictions, and the intended use. Requirements differ, but regulators have consistently focused on issues such as notice, purpose limitation, data minimization, consumer choice, and controls around sharing and profiling. In some contexts, combining datasets can create a level of sensitivity or identifiability that did not exist when records were separate.
For marketers, the main professional implication is that identity resolution cannot be treated as a purely technical operations project. Governance has to define:
- Which identifiers may be collected and stored
- How long they are retained
- What lawful basis or consent structure applies
- Which teams and partners may use matched data
- Whether the use case is targeting, measurement, service, suppression, or analytics
- How consumers can access, correct, or delete relevant information where required
This is especially important when organizations use identity data across multiple business functions. A customer may reasonably expect a login to support service continuity, but not expect all associated signals to be used for unrelated advertising purposes. Even where a practice is technically possible and contractually permitted, it may still create trust issues if the use feels opaque or overly invasive.
Why first-party data does not eliminate the hard parts
As privacy rules tightened and third-party data became less dependable, many marketers shifted attention toward first-party data. That shift is rational, but first-party data does not eliminate identity complexity.
First-party records are often fragmented across ecommerce, store systems, CRM platforms, loyalty programs, call centers, and regional databases. They may be governed by separate business units with different naming conventions and matching rules. A brand may own the systems but still struggle to reconcile customer records. In large organizations, internal fragmentation can be a bigger obstacle than external signal loss.
There is also a tendency to equate first-party data with consented data, which is not automatically true. Whether a first-party identifier can be used for cross-channel advertising, partner measurement, or extended profiling depends on the relevant disclosures, permissions, and applicable law. Ownership of the relationship does not remove the need for governance.
How marketers should evaluate identity claims
Identity vendors, CDPs, adtech platforms, and measurement providers often present identity as a solved layer that can be added to the stack. In reality, performance varies sharply by use case, data quality, geography, scale, and regulatory conditions.
A more useful evaluation approach starts with specific questions.
What is the system resolving: individuals, households, devices, or accounts? Which identifiers are used? Which matches are deterministic and which are inferred? How are confidence scores handled operationally? What are the observed false positive and false negative risks? How often is the graph updated? How are stale links removed? What privacy controls are built into matching and activation workflows? Can the provider explain where independent validation exists and where claims are model-based?
Marketers should also ask whether the use case actually requires identity resolution at the advertised level of granularity. Some planning, measurement, and optimization tasks can be done effectively with aggregated or cohort-based approaches. Not every business problem requires a persistent identity graph.
That matters because identity systems can add cost, complexity, and governance burden. The value is highest when better linkage changes a real business outcome, such as reducing duplicate media exposure, improving customer suppression logic, strengthening retention programs, or producing materially more credible measurement.
What changes, and what does not
Identity resolution changes how organizations organize and use data across fragmented channels. It can improve continuity between marketing, commerce, and service systems. It can make personalization and measurement less wasteful when done carefully. It can also help brands operate in environments where anonymous third-party tracking is less available than it once was.
What it does not change is the basic uncertainty of customer data. No identity layer makes consumer behavior fully observable. No graph eliminates the need for consent management, data stewardship, and human judgment. No match rate, however impressive, guarantees that a campaign is effective or that a message is welcome.
For advertising and marketing professionals, that is the central point. Identity resolution matters because so much modern marketing depends on connecting records across touchpoints. But a unified identity is never just a technical achievement. It is a probabilistic, governed, and purpose-specific model of customer relationships, built under real constraints and prone to real error.
The organizations that use identity resolution well tend to understand those limits. They treat identity not as a magic key to omnichannel certainty, but as an infrastructure discipline that supports better decisions when the data, permissions, and use cases genuinely justify it.
Leave a Reply