
A/B testing is often discussed as a digital optimization tool: a way to improve click-through rates, form completions, cart conversion, or email response by comparing one version of something against another. That description is accurate, but incomplete. For branding professionals, the more important point is that A/B testing is a form of consumer research built around controlled comparison. It can help organizations understand how specific changes in language, layout, offers, onboarding flows, and other touchpoints affect behavior. It can also be badly overinterpreted.
That distinction matters because brands are built through repeated signals and accumulated experience over time, while most experiments answer a narrower question: did one version of a particular stimulus produce a meaningfully different result than another for a defined audience under defined conditions? Used well, A/B testing sharpens brand expression and customer experience. Used poorly, it encourages tactical chasing at the expense of strategic coherence.
Understanding how A/B testing works begins with its research logic.
What A/B testing is actually testing
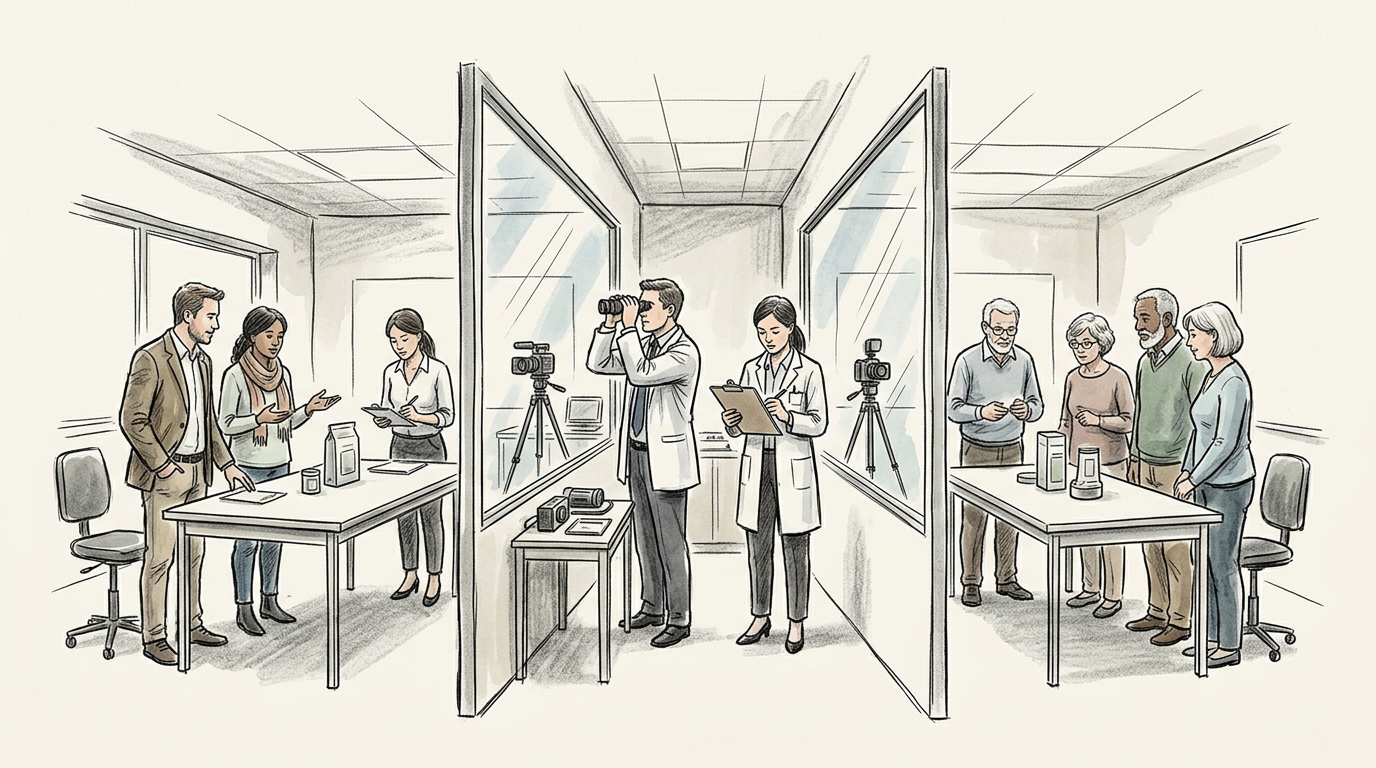
In its simplest form, an A/B test compares two versions of the same branded or commercial experience. Version A is usually the control, meaning the current or standard version. Version B is the treatment, meaning the new variation being tested. People are assigned to one version or the other, and researchers measure what happens.
The goal is not merely to ask which version people prefer in the abstract. The goal is to isolate whether a specific change appears to cause a measurable difference in an outcome. On a website, that might mean a higher product-detail click rate, lower checkout abandonment, or greater sign-up completion. In email, it could mean opens, clicks, unsubscribes, or downstream purchases. In messaging, it may involve response to value propositions, proof points, or calls to action.
For brand management, this is useful because many brand-relevant decisions are not purely aesthetic or conceptual. They are operational decisions about how brand meaning is expressed in moments that affect recognition, trust, clarity, and action. A company may want to know whether a category descriptor improves understanding of a new offer, whether emphasizing heritage increases perceived credibility, or whether a more explicit guarantee reduces anxiety during purchase. These are testable questions.
What A/B testing does not do on its own is settle broad strategic issues such as a brand’s long-term positioning, the wisdom of entering a new category, or whether a rebrand has strengthened brand equity over several years. Those are larger questions involving multiple variables, cumulative exposure, and often a longer horizon than a single experiment can capture.
Why random assignment matters
The central feature of an A/B test is random assignment. Participants, site visitors, or audience members are randomly allocated to version A or version B. In principle, randomization helps ensure that the groups are comparable. If the process is working properly, the two groups should be similar on average except for the difference introduced by the test.
That is what allows researchers to infer that outcome differences are more likely due to the treatment rather than to preexisting differences in the audience.
Without random assignment, comparisons become much less trustworthy. If one email subject line is shown mostly to high-value repeat customers and the other mostly to new prospects, observed differences may reflect audience composition rather than message performance. If one landing page version is mostly seen on mobile devices and the other mostly on desktop, the result may say more about device context than about branding or offer presentation.
In digital environments, randomization is usually handled by experimentation platforms, content management systems, ad tools, or product analytics systems. Even so, the principle remains the same: each eligible observation should have a known and unbiased chance of being placed into each test condition.
For branding teams, this methodological point is not academic. Many internal disagreements about messaging, navigation, naming cues, proof points, and customer experience can appear to be resolved by data when the underlying comparison was not actually fair. If traffic allocation, audience segmentation, timing, or channel context differs systematically across versions, the experiment may create false confidence.
Control and treatment groups are about comparison, not creativity
The language of control and treatment can sound clinical, but the logic is straightforward. The control group receives the current experience. The treatment group receives the revised experience. The observed difference between them becomes the basis for inference.
In practice, the control is valuable because it gives teams a baseline anchored in real behavior rather than opinion. A treatment can outperform, underperform, or show no meaningful difference at all.
For brand-related decisions, the choice of control matters a great deal. If the existing version already carries strong recognition cues, trusted language, or familiar navigation patterns, replacing them may affect not only immediate conversion but also confidence and comprehension. A treatment that appears fresher to internal teams may reduce fluency for customers who rely on established brand signals.
This is one reason A/B testing should not be reduced to “which design wins.” The test is not judging abstract taste. It is comparing outcomes produced by alternative executions in context. A new headline might drive more trial because it is clearer about the offer. A different package visualization might improve product understanding. A revised sign-up flow might reduce friction. Those are specific findings tied to a specific setup.
The inverse is also true. A weaker result does not necessarily mean the tested brand idea is strategically wrong. It may mean the specific execution failed to communicate the intended meaning effectively, or that the metric being observed captured short-term response but not broader brand value.
Outcome measurement determines what the test can tell you
A/B tests are only as useful as the outcomes they measure. In many commercial settings, the measured outcome is behavioral: clicks, purchases, account creation, repeat visits, time on task, churn, average order value, or redemption. Behavioral measures are often attractive because they are concrete and directly tied to business action.
But branding decisions frequently require a wider view of outcomes.
If the question concerns immediate transactional response, a short-term behavioral metric may be appropriate. If the question concerns comprehension, trust, or recognition, teams may need supporting measures such as survey responses, brand lift indicators, or follow-up behavior over time. If the test affects a critical brand touchpoint, such as onboarding, customer service messaging, or subscription cancellation, relying on a single conversion metric can be misleading.
Consider a test between two offer presentations. One may produce more immediate sign-ups because it uses more aggressive urgency language. Another may produce slightly fewer sign-ups but also fewer cancellations, fewer complaints, and stronger satisfaction later. The first result may look better if the organization measures only immediate conversion. The second may be better for brand trust and long-term economics.
This is where branding professionals have an important role. Brand equity is not captured by one metric. Awareness, recognition, perceived quality, trust, consideration, familiarity, and loyalty operate differently and over different time horizons. An experiment can help estimate the effect of a specific change on one or more of these dimensions, but only if the measures are chosen with care.
Statistical uncertainty is part of the result, not a technical footnote
A/B test results are always estimates drawn from observed data, not direct readings of permanent truth. If version B produces a higher conversion rate than version A in a test, that observed lift may reflect a genuine underlying effect, random variation, or a combination of both.
This is why statistical inference matters. Researchers use statistical methods to estimate how likely it is that an observed difference could have arisen by chance if there were actually no true difference between the versions. In many business settings, teams summarize this with a significance threshold or confidence level. The terminology varies by platform, but the underlying issue is uncertainty.
For non-specialists, two practical points are especially important.
First, a result that is not statistically persuasive should not be treated as proof that one version is better. Small differences can easily arise from random fluctuation, especially with limited sample sizes.
Second, a statistically persuasive result is still an estimate. It does not guarantee that the effect will repeat identically in every segment, season, channel, or market.
The U.S. Government Accountability Office, in its overview of program evaluation methods, describes random assignment as one of the strongest ways to identify causal effects when properly implemented because it helps separate treatment effects from other influences. That logic carries into commercial experimentation, but only when the design and analysis are sound. Similarly, the American Association for Public Opinion Research and academic statistics literature have long emphasized that uncertainty is inherent to inference from samples. Business experimentation is no exception.
In practical terms, branding and marketing teams should be cautious when results are based on short test windows, small populations, or many simultaneous comparisons. If a team runs dozens of tests or slices a result into many subgroups, some “wins” will appear by chance alone. The more aggressively organizations search for patterns, the more discipline they need in interpretation.
Practical significance is not the same as statistical significance
One of the most common misunderstandings in A/B testing is confusing statistical significance with business importance.
A result can be statistically significant yet trivial in practice. With a very large sample, even a tiny difference may register as unlikely to be due to chance. But if that difference has negligible revenue impact, no customer experience value, and no strategic relevance, it may not justify implementation.
The reverse can also happen. A result may point to a potentially valuable improvement but fail to reach conventional thresholds because the test did not have enough traffic or time. That does not prove the idea has no merit. It means the organization does not yet have strong enough evidence.
For brand management, practical significance often involves more than immediate lift. A small increase in conversion may not be worthwhile if it weakens premium cues, creates confusion in the portfolio, undermines trust, or fragments brand expression across channels. Conversely, a modest improvement in clarity at a high-friction touchpoint may be strategically important if it supports brand comprehension, reduces service burden, and strengthens customer confidence.
This is especially relevant in premium, luxury, regulated, and experience-led categories, where not every brand decision should be optimized for instant response. A test that boosts clicks by making claims more sensational may be counterproductive if it erodes credibility. A test that increases short-term uptake through heavier discount framing may conflict with a brand’s pricing architecture or perceived quality positioning.
Where A/B testing is most useful in brand-relevant work
A/B testing is most effective when the question is specific, the versions are clearly defined, and the measured outcomes are close to the experience being changed.
In branding-adjacent work, common applications include:
- Website and app journeys, such as navigation labels, onboarding flows, product-page structure, proof points, and checkout communication.
- Message framing, including whether customers respond better to convenience, expertise, savings, reassurance, innovation, sustainability, or other value cues.
- Offers and promotions, such as trial structures, bundles, guarantees, thresholds, and incentive presentation.
- Customer experience communications, including service notifications, waitlist updates, cancellation flows, account prompts, and retention messaging.
- Distinctive brand cues in execution, such as whether recognizable verbal or visual assets improve response without reducing clarity.
These areas matter because they sit at the intersection of behavior and meaning. A website headline is not only copy. It is also a positioning signal. A checkout reassurance message is not only conversion support. It is also a trust signal. An onboarding flow is not only product education. It is also a first lived expression of the brand promise.
Still, the strongest tests usually focus on one or two variables at a time. If teams change headline, imagery, offer structure, navigation, social proof, and pricing language all at once, the test may reveal that one total package outperformed another, but not why. That may be acceptable for tactical optimization, yet less helpful for learning that can guide broader brand management.
Why experiments answer narrow questions
This is the discipline’s key limitation and one of its greatest strengths. A/B testing answers narrow questions well when they are framed precisely.
Does adding a plain-language explanation of a complex product increase completion among first-time visitors?
Does emphasizing free returns reduce abandonment for a fashion brand where fit uncertainty is high?
Does showing the parent brand endorsement improve trust for a newer sub-brand?
Does a value proposition centered on time savings outperform one centered on cost savings for a particular audience in a particular channel?
These are answerable experimental questions.
By contrast, many broad branding questions are not directly resolved through a single A/B test. For example:
- Should the company reposition itself for a different audience?
- Does the corporate brand need to lead the portfolio more visibly?
- Will a new name create stronger long-term meaning than the current one?
- Has a rebrand improved reputation or cultural relevance over several years?
Those questions involve accumulated exposure, competitor response, organizational behavior, media context, public interpretation, and changing market conditions. Experiments can contribute evidence, but they do not provide total answers.
This distinction protects against a common management error: treating experimentally optimized fragments as a substitute for brand strategy. Brands require coherence across product, service, pricing, communications, identity systems, and customer experience. A set of isolated local improvements does not automatically add up to a stronger brand.
A/B testing and brand positioning
A/B testing can support positioning work, but it does not create positioning by itself.
Positioning is a strategic choice about how a brand seeks to be understood relative to alternatives. It involves target audience, frame of reference, differentiation, value proposition, and reasons to believe. Experiments can help refine the way that positioning is expressed. They can test whether one articulation is clearer, more credible, or more motivating than another in a given context.
For instance, a B2B software brand may have chosen to position around risk reduction rather than speed. An experiment can compare two product-page versions that both support that strategic position but frame proof differently: one emphasizing compliance credentials, another emphasizing uptime and support responsiveness. The test may help identify which proof point better strengthens response for a defined audience.
That is different from using A/B testing to let isolated channel performance determine the position itself. If repeated short-term tests push messaging toward whatever produces the strongest immediate click response, brands can drift away from coherent strategic meaning. Over time, that can weaken differentiation, create inconsistency across touchpoints, and confuse both prospects and internal teams.
Distinctiveness, recognition, and the testing of brand assets
Branding professionals often distinguish differentiation from distinctiveness. Differentiation refers to meaningfully perceived differences. Distinctiveness refers to cues that help people identify and recognize the brand.
A/B testing can be useful in evaluating how distinctive assets function in market-facing execution. Teams may test the presence or absence of a recognizable color field, mnemonic phrase, character, package shape representation, or parent-brand endorsement to see whether these elements aid recognition or improve response in specific settings.
But experimentation here should be interpreted carefully. A distinctive asset can be valuable even if its short-term performance effect is modest, because recognition often compounds over repeated exposure. Research from the Ehrenberg-Bass Institute has emphasized the importance of mental availability and the role of distinctive brand assets in helping brands come to mind and be noticed in buying situations. That body of work is broader than any single A/B test and reminds practitioners that recognition effects may extend beyond the immediate conversion event.
This is why organizations should avoid stripping away familiar assets simply because an isolated variant produced a slight short-term lift. If a brand removes recognizable cues in favor of a cleaner or more generic presentation, it may gain momentary simplicity while losing memory structure that supports future recognition.
What A/B testing can and cannot say about customer experience
Because customer experience strongly influences brand perception, experimentation is often valuable beyond advertising and promotional messages. Service scripts, FAQ structures, app notifications, billing explanations, return policies, and onboarding sequences can all be tested.
In these situations, the brand issue is not merely whether the language is efficient. It is whether the experience reinforces the expectations the brand creates. A brand positioned around ease should reduce friction in service interactions. A brand positioned around expertise should communicate competence and clarity in moments of uncertainty. A brand positioned around care or transparency should avoid confusing fees, evasive copy, or opaque cancellation procedures.
A/B testing can help identify which experience design better supports those goals. Still, the measured outcome should match the question. If a cancellation flow reduces churn by making exit harder rather than by creating more value, a superficial success metric can hide reputational damage. If service language reduces call volume but leaves customers feeling misled, the experiment may improve operational efficiency while weakening trust.
For this reason, experiments involving customer experience often benefit from multiple measures, including immediate behavior, complaint rates, satisfaction, repeat usage, and sometimes qualitative follow-up.
Common errors in business use of A/B testing
The mechanics of testing are easy to describe, but organizational misuse is common. Several errors recur across industries.
One is testing without a meaningful hypothesis. If teams do not articulate why the treatment might outperform the control, they learn less even when they find a winner. Another is overloading a test with too many changes, making interpretation difficult. A third is ending tests too early when early results appear promising, which increases the chance of acting on noise rather than stable evidence.
Brand-related work introduces additional risks. Teams may optimize for immediate conversion in ways that erode trust, make the brand sound interchangeable with competitors, or damage portfolio clarity. They may test channel-level messages that conflict with the broader brand position. Or they may ignore heterogeneity, assuming that a result for one segment, geography, or lifecycle stage should be generalized everywhere.
There is also a governance risk. If every team independently tests language, offers, and interfaces without a clear brand framework, local optimization can produce fragmented expression. One channel may learn that urgency works. Another may find reassurance more effective. A third may simplify category language to the point that premium differentiation disappears. None of those findings is necessarily wrong on its own, but together they can create a brand that is behaviorally optimized in parts and strategically incoherent as a whole.
How branding teams should work with experimentation
Brand stewardship does not require resisting experimentation. It requires framing it properly.
A useful approach is to begin with strategic guardrails. What aspects of the brand’s positioning, trust cues, architecture, pricing logic, or distinctive assets are central enough that tests should work within them rather than casually override them? Which variables are open for optimization, and which are foundational to long-term recognition and equity?
Within those guardrails, teams can use experiments to improve how the brand shows up in lived experience. Messaging can be made clearer. Offers can be made easier to understand. Navigation can better match customer expectations. Endorsement structures can be tested for clarity. Distinctive verbal or visual cues can be assessed for whether they help or hinder response in context.
The key is to treat A/B testing as a disciplined learning system, not as a substitute for brand judgment. Strong organizations combine experimental evidence with qualitative research, brand tracking, behavioral data, customer feedback, and strategic analysis. They ask not only “did it lift?” but also “what did customers likely perceive?” and “does this strengthen the brand we are trying to build?”
What professionals should take from A/B testing
At its best, A/B testing is one of the clearest examples of how consumer research can inform brand expression in market reality. Through random assignment, control and treatment comparison, defined outcome measurement, and explicit attention to statistical uncertainty, it offers a more credible basis for learning than intuition alone.
Its value for branding lies in precision. It can help teams evaluate how specific choices in websites, messaging, offers, and customer experience affect customer behavior and, in some cases, perceptions tied to trust, clarity, and recognition. It can reveal friction that undermines the brand promise. It can show whether an expression of positioning is landing as intended. It can help improve execution at moments where brand meaning becomes concrete.
Its limitation is equally important. Experiments answer narrow questions. They do not eliminate uncertainty, replace strategic judgment, or fully capture long-term brand equity. A brand is not built by test results alone, and not every high-performing variant is good brand management.
For AAMA readers working across agencies, brands, media, research, and product teams, the practical lesson is straightforward. Use A/B testing to make better evidence-based decisions about how the brand is expressed in specific situations. But keep those tests connected to the larger system of positioning, recognition, trust, experience, and reputation that gives branding its enduring value.
Leave a Reply