
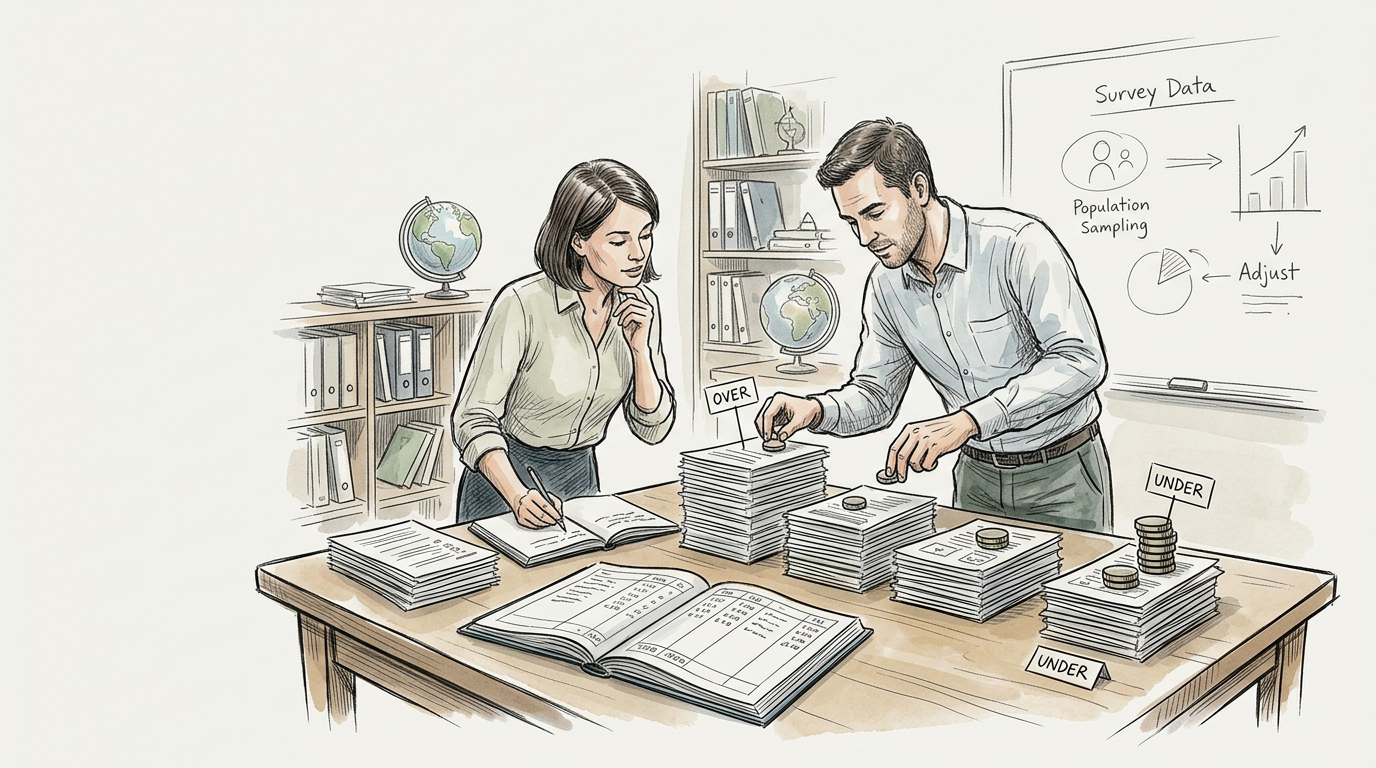
Brand decisions are often made from survey evidence that appears precise but is, in practice, conditional. A brand team may see that awareness is 42 percent, that consideration rose three points, or that one segment responds better to a new positioning statement than another. Yet those results do not come directly from “the market.” They come from a sample, and samples rarely mirror the population perfectly. Weighting is one of the main tools researchers use to make survey data more representative of the people a brand actually needs to understand.
For branding professionals, that matters because many brand questions are unusually sensitive to who is overrepresented or underrepresented in a sample. Measures such as aided awareness, unaided recall, perceived distinctiveness, trust, relevance, usage, and preference can shift materially depending on age, geography, income, tenure in category, or current customer status. If a sample contains too many heavy category buyers, digitally active consumers, loyal customers, or people from one region, the resulting portrait of brand equity can be distorted. Weighting helps correct some of that distortion, but it is not a magic fix, and misunderstanding it can lead to overconfidence in weak brand evidence.
What weighting does, in plain terms
In survey research, weighting adjusts the contribution of each respondent so that the final dataset better reflects known characteristics of the target population. If younger respondents are overrepresented and older respondents are underrepresented, a researcher may assign lower weights to the younger group and higher weights to the older group. The goal is not to change what any individual said. It is to make the combined estimates more aligned with the market being studied.
The American Association for Public Opinion Research describes weighting as a way to compensate for unequal selection probabilities, nonresponse, and coverage differences when those factors are understood and when benchmark information is available. In practice, researchers often weight to external targets such as census demographics, industry panels, customer-file distributions, or other validated population benchmarks. Common methods include post-stratification, raking, and calibration, depending on the design and the available control totals.
For brand research, the population benchmark might be the adult population, category buyers, business decision-makers, a client’s active customers, or another clearly defined audience. That definition is strategically important. A brand tracker intended to guide broad market positioning should not necessarily be weighted the same way as a study focused on current account holders, loyalty members, or enterprise procurement teams. Before weighting begins, researchers must decide whose perceptions are relevant to the brand question.
Why weighting matters in branding research
Branding is shaped by perception, memory, and recognition across audiences, not just by product performance or media delivery. That makes representativeness especially important.
Suppose a financial services brand is assessing trust and familiarity across the national market. If the sample skews toward current customers, trust and familiarity will likely appear stronger than they are among prospective customers. If a health care brand is evaluating a naming change, and the sample overindexes on highly engaged users who have already received brand communications, recognition of the new name may look artificially high. If a consumer packaged goods company is testing packaging cues as distinctive assets, a sample dominated by heavy category users may overstate how easily average buyers can identify the brand from color, shape, or pack structure.
In each case, weighting can help align the data to the intended audience. That improves the strategic usefulness of the findings. It does not make the survey perfect, but it reduces one common source of bias: the mismatch between the sample composition and the population composition.
This is particularly relevant in work involving:
- brand awareness and recognition, where demographic and category-use distributions often matter;
- brand equity tracking, where trends can be distorted by shifts in sample mix from wave to wave;
- repositioning and rebranding studies, where early adopters or loyalists may be disproportionately likely to respond;
- brand architecture research, where current customers of one sub-brand may dominate the sample and obscure perceptions of the parent brand or adjacent offers;
- B2B brand studies, where firm size, job function, purchase authority, and industry can all materially affect results.
How researchers create weights
Although the mechanics vary, the general process is straightforward. Researchers begin with a target population and a set of trusted benchmarks describing that population. They then compare the achieved sample against those benchmarks and compute adjustment factors.
For example, if 18-to-34-year-olds make up 30 percent of the target population but 40 percent of the sample, respondents in that group would be down-weighted. If people 55 and older make up 25 percent of the population but only 15 percent of the sample, respondents in that group would be up-weighted. The same logic can apply simultaneously across multiple variables such as age, gender, region, race and ethnicity, education, or category incidence.
One widely used method is iterative proportional fitting, commonly called raking. The Pew Research Center has published detailed methodological explainers on weighting in survey practice, including the use of raking to align samples with known population parameters. Raking adjusts the sample repeatedly across multiple margins until the weighted distribution matches the target benchmarks closely enough. This is often useful when a brand study needs to reflect several dimensions at once rather than a single quota variable.
In customer research, weighting may also be based on known business data. A telecom provider, for instance, might weight survey respondents to reflect its customer base by region, tenure, plan type, and revenue tier. That can be appropriate if the research objective is customer experience or retention strategy. It may be less appropriate if the objective is broader brand positioning among the competitive market.
Weighting changes the answer because it changes whose answers count more
That may sound obvious, but it is important to state clearly. A weighted result is not the “real” result and the unweighted figure is not automatically “wrong.” They are answers to slightly different questions.
The unweighted result describes the achieved sample. The weighted result estimates the target population, assuming the weighting variables are relevant and the benchmarks are accurate. If those assumptions are sound, the weighted estimate is usually more decision-useful. If those assumptions are weak, weighting can create a false sense of correction.
This distinction matters in brand discussions because teams sometimes compare weighted and unweighted numbers as if one were a cleaner version of the other. In fact, the difference can reveal where the sample was skewed and which groups are driving the brand measures. If aided awareness rises from 48 percent unweighted to 55 percent weighted, that means the underrepresented groups receiving more weight are more aware of the brand than the overrepresented groups receiving less. That is analytically meaningful. It may point to real differences in market structure, distribution, category participation, or audience composition.
Brand metrics are especially sensitive to weighting choices
Not every metric moves equally when weights are applied. Factual questions with little variation across groups may change only slightly. Brand measures often move more because they are shaped by familiarity, culture, media exposure, income, age, geography, and category behavior.
Consider a few common examples:
Awareness estimates can change materially if the sample overrepresents people with higher category involvement or heavier media consumption. A national consumer brand may appear more mentally available than it really is if the sample disproportionately includes urban, affluent, and digitally connected consumers.
Brand trust and reputation scores can shift when current customers are overrepresented. Existing users generally know more about the brand and often report more confidence than nonusers, though dissatisfied customer groups can also be missed if response rates are uneven.
Distinctive asset testing can be affected by category expertise. Heavy users of a category may recognize colors, pack shapes, taglines, or sonic cues more easily than occasional buyers. A weighting scheme that better reflects true buying frequency can temper overstatements of recognizability.
Positioning research can also be sensitive. If one audience segment is more likely to respond to surveys and also more likely to like a proposed positioning territory, the brand team may mistakenly believe the idea has broad strategic potential. Weighting can partially correct that if the segment is identifiable and benchmarkable.
Why weighting increases variance and creates design effects
Weighting improves representativeness, but it usually comes at a cost. When some respondents count much more than others, the effective statistical efficiency of the sample declines. This is often summarized through a design effect, commonly shortened to deff.
The basic idea is well established in survey methodology: unequal weights increase the variance of estimates relative to a simple random sample of the same nominal size. A classic approximation associated with survey sampling work by Leslie Kish expresses the weighting effect in relation to the variability of the weights. In practical terms, the more unequal the weights, the less information the sample effectively contains.
For brand teams, this matters because weighted findings can look more precise than they are. A tracker may report n = 1,000 interviews, but if heavy weighting is required, the effective sample size may be meaningfully lower. That means wider confidence intervals and a greater chance that small differences or wave-to-wave movements are noise.
This is not an argument against weighting. It is an argument for reading weighted brand data with methodological discipline. If a brand health tracker shows a two-point increase in consideration after weighting, the key question is not whether weighting is bad. The key question is whether that change exceeds the likely variance of the estimate after accounting for the weighting design effect and the rest of the sample design.
In other words, weighting can make an estimate more representative while also making it less precise. Both can be true at once.
Extreme weights are a warning sign, not just a technical detail
The need for very large or very small weights often signals a problem in recruitment, coverage, or target definition. If a small number of respondents must carry an outsized share of the final estimate, the results can become unstable. A few unusual answers in a heavily weighted subgroup may move topline brand metrics more than expected.
Researchers often manage this risk through trimming or capping weights, balancing the desire for representativeness against the danger of excessive variance. But trimming introduces its own tradeoff. It reduces the influence of extreme cases, which can improve stability, yet it also pulls the weighted sample somewhat away from the benchmark targets.
For branding applications, extreme weights should trigger substantive questions:
- Did the recruiting source underreach a strategically important audience?
- Was the survey too long or too difficult for certain groups to complete?
- Did screening criteria unintentionally favor one segment of category users?
- Is the target population defined too broadly for the available sample source?
- Are there meaningful perception differences between the underrepresented group and everyone else?
Those are not merely methodological concerns. They affect how confidently a brand team should act on the findings. A repositioning decision, naming choice, or architecture simplification should not rest heavily on groups that were difficult to recruit and then statistically amplified unless the limitations are well understood.
Weighting relies on assumptions, and those assumptions should be visible
Weighting works best when the variables used for adjustment are related both to response propensity and to the survey outcomes. If younger consumers are less likely to respond and also differ from older consumers in awareness, trust, or preference, weighting on age can help. But if the main difference lies in something not captured by the weighting variables, such as attitudes toward the category, digital fluency, political identity, or brand loyalty, then weighting may not remove the bias.
This is one of the most important limits for brand professionals to understand. Weighting can only adjust for factors that are measured and benchmarked, directly or indirectly. It cannot guarantee that late responders, panel members, or recruited participants represent nonresponders in all the ways that matter for brand perception.
The National Academies, AAPOR, and major survey organizations have repeatedly emphasized this broader point in different contexts: statistical adjustment is useful, but it does not erase selection bias when the underlying participation mechanism is strongly related to the study topic and not fully observed.
In branding, this limitation is often acute because attitudes toward brands are themselves tied to who chooses to participate. Highly opinionated customers, fans, critics, heavy buyers, and promotion-sensitive shoppers may be more likely to respond. If a sample source disproportionately reaches people who are already more engaged with brands or with the category, weighting to demographics alone may leave important bias in place.
Why weighting cannot repair every recruitment problem
It is tempting to treat weighting as a rescue tool. A sample came in skewed, so weights will fix it. Sometimes they help substantially. Sometimes they only make a flawed sample look more polished.
There are several problems weighting cannot solve well.
First, weighting cannot create representation for people who are barely in the sample or missing entirely. If a study about a regional grocery brand reaches very few rural households, weighting cannot manufacture the range of attitudes held by rural consumers. It can only increase the influence of the few rural respondents who were interviewed.
Second, weighting cannot correct poor coverage. If the sample frame systematically misses an audience, such as lower-connectivity consumers, non-English speakers, smaller business buyers, or infrequent category purchasers, no statistical adjustment can fully substitute for direct inclusion.
Third, weighting cannot fix bad screening or an unclear target population. If a brand tracker intended to represent category buyers accidentally overincludes brand loyalists or promo hunters because of how screening questions were structured, weights may not recover the intended market view unless reliable benchmarks for the true target are available.
Fourth, weighting cannot resolve measurement error. If respondents misunderstand the brand name, confuse the parent brand with a sub-brand, misidentify a package, or answer awareness questions carelessly, the issue is instrument quality, not sample composition.
That last point is especially relevant in branding research. Brand architecture, naming, and distinctive asset studies are vulnerable to confusion effects. If respondents do not know whether they are evaluating the corporate brand, a product line, or a recently acquired endorsed brand, weighting will not clarify the meaning of their answers.
Weighting and trend interpretation in brand trackers
Ongoing brand tracking programs create another challenge: consistency over time. A weighted tracker may be more representative in each individual wave, but changes in weighting schemes, benchmark sources, or sample suppliers can alter trends independently of any true market movement.
That does not mean weighting should be avoided in tracking. It means methodology changes should be documented and interpreted carefully. If a brand sees awareness dip after a sample vendor change, the right question is whether the market shifted or whether the mix of respondents and resulting weights changed. If a tracker adopts improved benchmark controls partway through the series, the break in trend may reflect a better estimate rather than a deterioration in brand health.
For this reason, experienced researchers often review both weighted and unweighted trend lines, monitor average weight size and weight variability by wave, and report effective sample size rather than only nominal completes. That level of discipline helps prevent false narratives about brand growth or decline.
For brand management, this is more than a technical reporting issue. Long-term decisions about position, investment, creative platform, portfolio support, and channel emphasis are often justified with tracker evidence. If the weighting approach shifts quietly, management may attribute methodological artifacts to changes in consumer meaning.
What branding teams should ask when reviewing weighted survey findings
Brand leaders do not need to become survey statisticians, but they should ask sharper questions before using weighted results to support strategic decisions. Useful questions include:
- What population is this study intended to represent?
- Which variables were used for weighting, and what benchmarks were they matched to?
- Are those benchmarks external and validated, or internal and estimated?
- How different are the weighted and unweighted results on key brand measures?
- What is the design effect or effective sample size after weighting?
- Were any extreme weights trimmed or capped?
- Which audiences were hardest to recruit, and how might that affect interpretation?
- Are there important brand-relevant variables that were not available for weighting?
These questions are especially important when research is being used to support consequential brand actions such as a repositioning, a corporate renaming, a portfolio simplification, a trust recovery effort, or a major investment in distinctive assets. In those contexts, methodological uncertainty should be part of the discussion, not hidden in appendices.
Weighting improves usefulness when it is tied to the real brand question
The most defensible weighting strategy is one aligned to the actual decision being made. If the question is about national brand awareness, weights should reflect the relevant market population. If the question is about perception among likely switchers in a category, then the target and benchmarks should reflect likely switchers, not just general adults. If the question concerns customer experience within an installed base, internal customer-file benchmarks may be entirely appropriate.
That alignment sounds basic, but it is often where brand research goes wrong. Surveys are sometimes weighted to what is easiest to benchmark rather than what is strategically most relevant. Demographics may be available, while brand usage, purchase authority, retailer mix, or category tenure may be more important for the decision. The result can be a technically weighted dataset that still misses the central source of brand bias.
For branding work, representativeness is not only demographic. It is also behavioral and competitive. A brand is interpreted through category experience, alternatives considered, prior exposure, and cultural context. Weighting can support better inference when those realities are incorporated thoughtfully. It becomes much less powerful when it is treated as a generic end-stage correction.
The broader lesson for brand management
Weighting is a valuable tool because brand decisions need population-aware evidence, not just convenient sample feedback. It helps researchers compensate for imbalances, reduce some forms of bias, and produce estimates that are more relevant to the audiences brands serve or seek to reach. In studies of awareness, equity, recognition, trust, reputation, or positioning, that adjustment can materially change the story a dataset tells.
But weighting does not absolve teams from defining the right population, recruiting it competently, designing clear instruments, and interpreting uncertainty honestly. It can improve a survey’s usefulness while also increasing variance. It can correct known imbalances while leaving unknown ones untouched. It can help a sample resemble the market on paper without fully resolving why certain people did or did not participate.
That is why weighting should be understood as part of brand measurement discipline, not as a technical afterthought. Brand strategy depends on credible readings of consumer perception. When practitioners understand what weighting changes, what assumptions it relies on, and where its limits lie, they are better equipped to separate meaningful brand signals from artifacts of sample construction. In an environment where small metric shifts can trigger major brand decisions, that distinction is not statistical trivia. It is part of responsible brand management.
For readers who want deeper methodological background, the American Association for Public Opinion Research provides standards and guidance at https://aapor.org, and the Pew Research Center has published accessible explainers on survey weighting and adjustment at https://www.pewresearch.org.
Leave a Reply